How Often SaaS Companies Should Conduct Penetration Tests
Annual testing alone misses the constant changes SaaS products undergo between assessments.
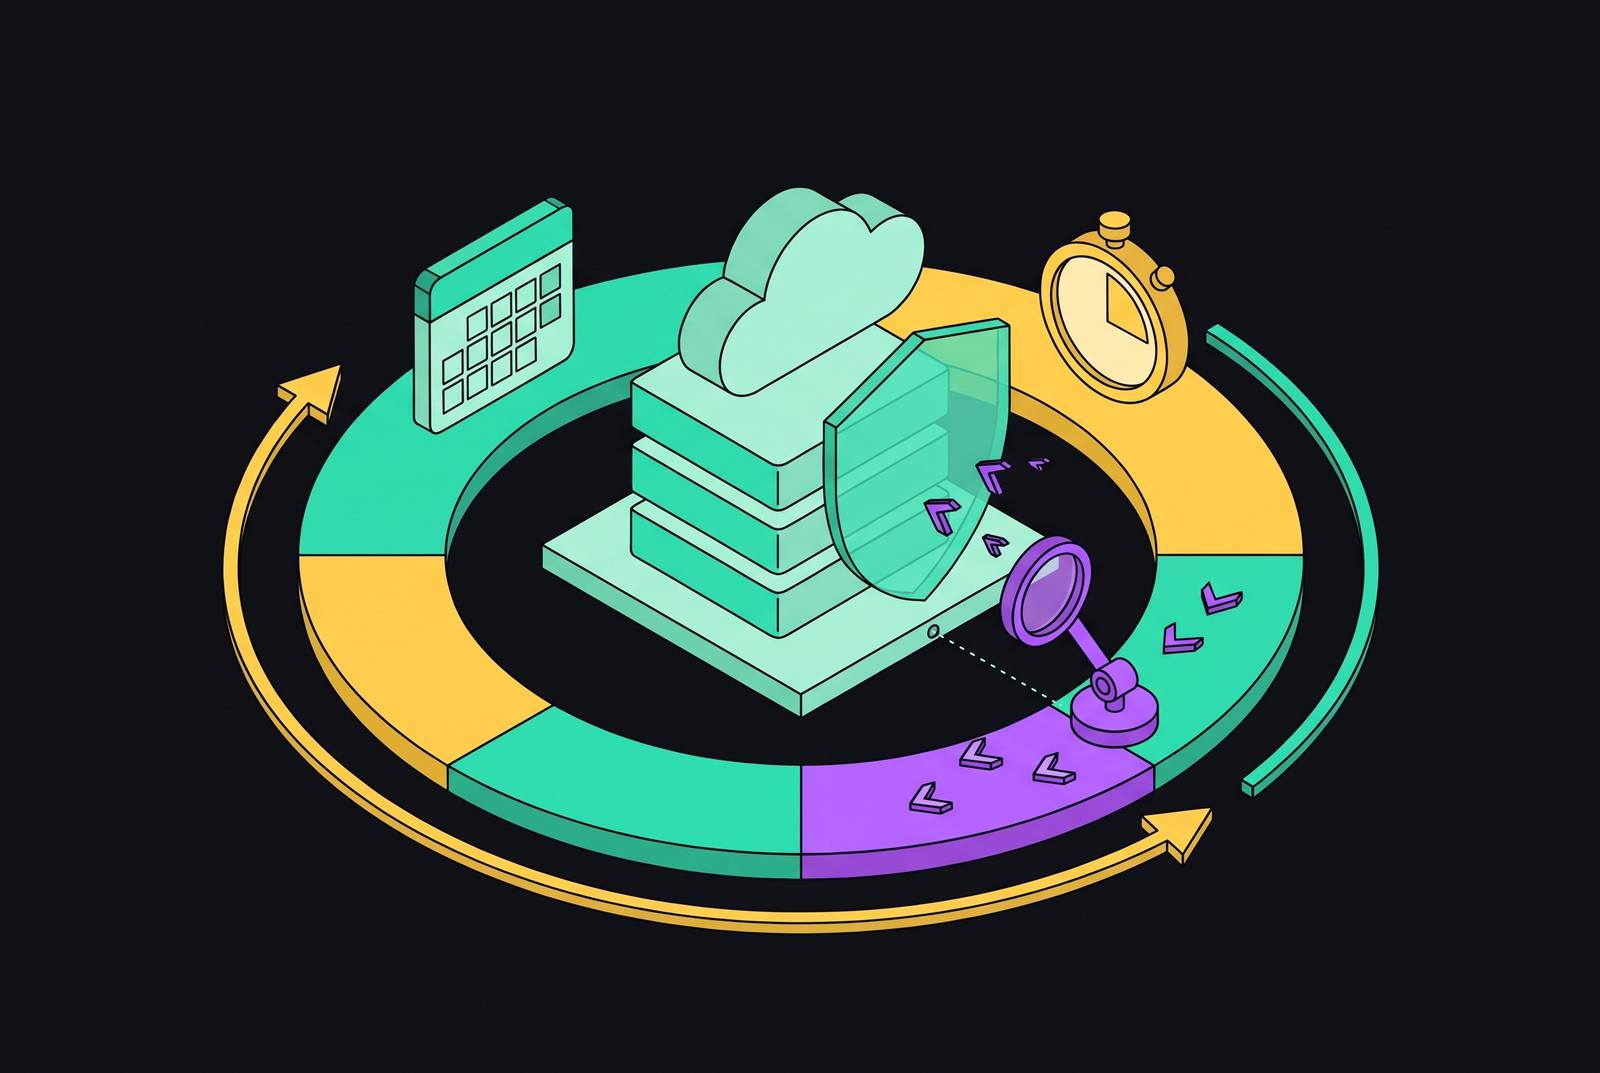
SaaS companies should conduct penetration tests at least annually, but the right frequency depends on how quickly the product changes and what it puts at risk. A sound program combines full-scope baseline tests, focused tests after significant changes, and continuous scanning between engagements. The calendar sets the minimum. Releases, infrastructure changes, and data sensitivity determine when more testing is needed.
Why annual pen testing no longer matches how SaaS products change
A SaaS team deploying multiple times per week can change much of its application between annual tests. Each release adds code that the last test never checked, so the report says less and less about the product running in production. The calendar does not capture that drift. An annual test still provides a useful foundation, but it cannot establish that changes made afterward are secure.
Third-party integrations, updated dependencies, and cloud configurations follow their own timelines, independent of the team’s planned feature work. Tenant isolation makes this especially dangerous for SaaS. A request that exposes another tenant’s data can be structurally valid, so a scanner cannot reliably distinguish it from an allowed request. Finding that failure takes human judgment about who should be able to access what, and that judgment needs revisiting as the application evolves.
What the attack surface of a SaaS product actually looks like under adversarial conditions
The surface that needs testing extends well beyond the customer-facing web pages. An API-first SaaS product can include internal and undocumented endpoints, background job processors, webhook signature checks, OAuth/SAML flows, and file upload and storage boundaries. These are parts of the application where access, identity, and data movement meet, yet scanners and narrow assessments routinely miss them.
Subscription and billing logic also needs testing because the product’s rules define how it should work. A tester needs to examine plan tier manipulation, payment gateway webhook tampering, and feature gate bypasses. A successful request is not necessarily an authorized one. Automated tools cannot work out those business rules on their own, so a skilled tester must check what the code does against what each subscription should allow.
Third-party connections take the trust boundary beyond the code the company controls. OAuth app installations, Zapier/Make connectors, and marketplace plugins each add relationships that a test must account for. Deployment pipelines belong in scope too. Long-lived credentials used to authenticate those pipelines often appear in findings, so secrets management is part of keeping the product secure, with risks that go beyond housekeeping. A sprint that changes any of these surfaces can change the paths available to an attacker.
The three-layer frequency model: baseline, event-triggered, and continuous
A comprehensive annual test is the minimum defensible baseline. It should cover the external perimeter, internal privilege escalation paths, cloud configuration, APIs, and tenant isolation, with whitebox access to source code, configurations, and documentation. That breadth gives the assessment its value. It also produces the evidence auditors, enterprise customers, and regulators request, rather than a report limited to the login page and a few authenticated routes.
Event-triggered tests check changes that cannot wait for the next baseline test. Major releases involving authentication, authorization, or tenant boundaries should trigger focused testing, as should infrastructure migrations, cloud provider changes, new integrations, and marketplace plugins. New user roles, permission models, or multi-tenancy tiers also qualify. A significant enterprise deal or compliance audit can create a separate need for recent evidence. These tests usually focus on the changed surface.
Continuous scanning fills the space between those engagements. Scanning every pull request can catch common injection flaws, misconfigured access controls, and exposed secrets before the code goes into production. It does not replace a human tester. Automated tools surface signals, while a certified tester interprets them, connects findings, and tests whether an attack is actually possible.
How stage and risk profile calibrate the baseline cadence
Teams should set the baseline based on how fast they deploy, how sensitive their data is, and which regulations they face, as well as company size. For an early-stage SaaS company before Series A, a good place to start is a full test each year plus event-triggered tests. That supports early SOC 2 and ISO 27001 efforts. Focused tests matter most when the product changes fast and the security team has few staff. An enterprise deal or audit should trigger testing before the next annual cycle.
For an active B2B SaaS product at Series A–B, twice-yearly testing is the stronger baseline. New integrations, enterprise tiers, and regions can expand the surface faster than an annual engagement can track. Growth creates both a coverage problem and a budget decision. A company’s funding stage helps locate it in the model, but the pace and consequences of its changes may require more frequent testing.
Fintech, healthtech, and other SaaS products handling sensitive regulated data should use quarterly testing as their baseline. Breaches cause more harm, checks are stricter, and buyers often ask for recent evidence before they buy. Products sold to enterprises or subject to strict regulations may need continuous human testing, with people assigned to triage findings as they come in. That is different from continuous automated scanning. It is appropriate when regulatory scrutiny is real-time or a breach would have immediate, material consequences for customers or reputation.
What compliance frameworks actually require versus what auditors expect in practice
PCI DSS v4.0 makes the scheduling requirement explicit. Requirement 11.4 mandates annual internal and external penetration testing, plus testing after significant changes to the cardholder data environment. Other frameworks leave more room for risk-based decisions, but that flexibility does not mean a company can assume test evidence will be unnecessary.
The AICPA’s Trust Services Criteria mention penetration testing only in a point of focus. SOC 2 therefore does not impose a blanket, named penetration testing cadence, but auditors and buyers can still expect evidence that the relevant controls work. Literal reading is not the whole exercise. A company that treats the absence of a fixed interval as permission to skip testing can find itself without the evidence an assessment or sale requires.
ISO 27001:2022 takes a risk-based approach through controls including Annex A 8.8, management of technical vulnerabilities, and Annex A 8.29, security testing in development and acceptance. ISO/IEC 27002:2022 names penetration testing in its guidance on how to put the controls into practice. Applicability is the key distinction here. If those controls appear in the Statement of Applicability and no test evidence exists, an auditor has grounds for a nonconformity.
HIPAA now requires risk analysis and periodic technical evaluation, but leaves open the choice of penetration testing as the method. Under HHS’s proposed rulemaking published January 6, 2025, vulnerability scans would be required at least every six months and penetration testing at least every 12 months. The proposal’s comment period closed March 7, 2025, and final action is targeted for July 2027 at the earliest.
These differences should not turn one assessment into several disconnected compliance exercises. A rigorous test conducted to PCI DSS methodology standards can meet methodology expectations across SOC 2, ISO 27001, HIPAA, and NIS2. Scope still needs to follow genuine threats. Meeting these shared testing expectations leaves other duties under each framework to meet, but avoids separate, weaker tests based on the narrowest reading of each one.
The vulnerability classes that most SaaS pen tests actually surface — and why they compound when left undetected between cycles
Broken access control is a direct threat to tenant isolation. An endpoint may expose an object identifier and trust the client to request only resources it owns, creating an opening for access to another tenant’s data. OWASP Top 10:2025 ranks broken access control first. Broken access control is a well-understood flaw whose consequences become especially serious when several customers share one application.
Server-side request forgery, or SSRF, is another concern for products that accept user-supplied URLs through webhooks, image uploaders, or “fetch from URL” features. It can expose internal network services and cloud metadata endpoints, with variants involving DNS rebinding, IPv6 bypasses, and cloud-internal services including the Kubernetes API. Insecure deserialization presents a different route to severe impact. Where a deserialization mechanism can instantiate arbitrary objects and invoke arbitrary methods, it can lead directly to remote code execution.
Other findings include missing HTTPS, weak password hashing, hard-coded keys, predictable tokens, and exposed pipeline secrets. A tester can chain SSRF with an IAM misconfiguration and an exposed internal service to produce critical impact from findings that initially appear less severe. Longer gaps between tests give those flaws more opportunities to interact with new code. Whitebox access helps the tester identify those relationships across the stack instead of discovering each weakness separately through external probing.
How whitebox testing changes what a pen test can find — and why scope is where most programs fail
Testing more often does little if each test covers the same small part of the product. Blackbox testing treats the application as an external attacker would, without access to its internals, which limits visibility into internal APIs, background processors, shared caches, and infrastructure-as-code configurations. Greybox testing gives the tester limited credentials but no access to code. That lets the tester cover more, but still leaves them without a full map of authorization logic, tenant enforcement, or how application code and cloud settings work together.
Whitebox testing gives the tester source repositories, product documentation, and cloud configurations such as Terraform, CloudFormation, or Pulumi. Those materials make it easier to map attack paths step by step. Access requires more trust and coordination with the testing partner. That coordination is useful because the tester can connect findings to the actual stack rather than rely only on what external probing reveals.
An engagement limited to a login page and a few authenticated routes can leave integration callbacks, webhook validation, OAuth/SAML edge cases, cross-tenant cache poisoning, and storage isolation untouched. A clean report then says little about those risks.
A certified tester tests whether weaknesses can be chained into an exploitable path and signs off on the results presented to auditors and customers. Every finding should have a working exploit. Without that proof, a team can spend too much effort on low-risk issues while underestimating a chain with much greater impact.
Building the cadence into the development lifecycle rather than scheduling around it
To make this model operational, teams should treat the annual baseline as a planned engineering milestone. The full-stack whitebox assessment should feed remediation priorities for the following quarter. Release planning should handle the focused tests. A definition of “major release” that flags authentication changes, tenant-boundary logic, integrations, and user roles makes testing a consequence of change.
Pull-request scanning should sit in the CI/CD pipeline so that common regressions are caught continuously. Findings from either scanning or human testing then need remediation and retesting. On-demand retesting should therefore be a requirement when selecting a testing partner, while a dedicated communication channel lets the security team and partner retain context about the architecture and threat model between engagements.
For teams pursuing compliance, this work also produces audit-ready evidence. Reports can map findings to Trust Services Criteria or Annex A controls and include an attestation letter without becoming a separate security exercise. Testing follows decisions about the product’s releases and infrastructure, fixes are tested again, and what the team and partner learn helps them focus later tests.